Fast LeWorldModel
Xi'an Jiaotong University | †Corresponding author
Open-Loop Rollout Visualization
Two-Room
start
goal
LeWM
Fast-LeWM
Reacher
start
goal
LeWM
Fast-LeWM
Planning
Cube
Sequential rollout
Parallel prefix
PushT
Sequential rollout
Parallel prefix
Abstract
Joint-Embedding Predictive Architectures (JEPAs), including LeWorldModel (LeWM), are promising reconstruction-free visual world models. However, LeWM evaluates candidate action sequences through repeated one-step latent transitions, which makes planning slow and allows latent prediction errors to accumulate over long horizons.
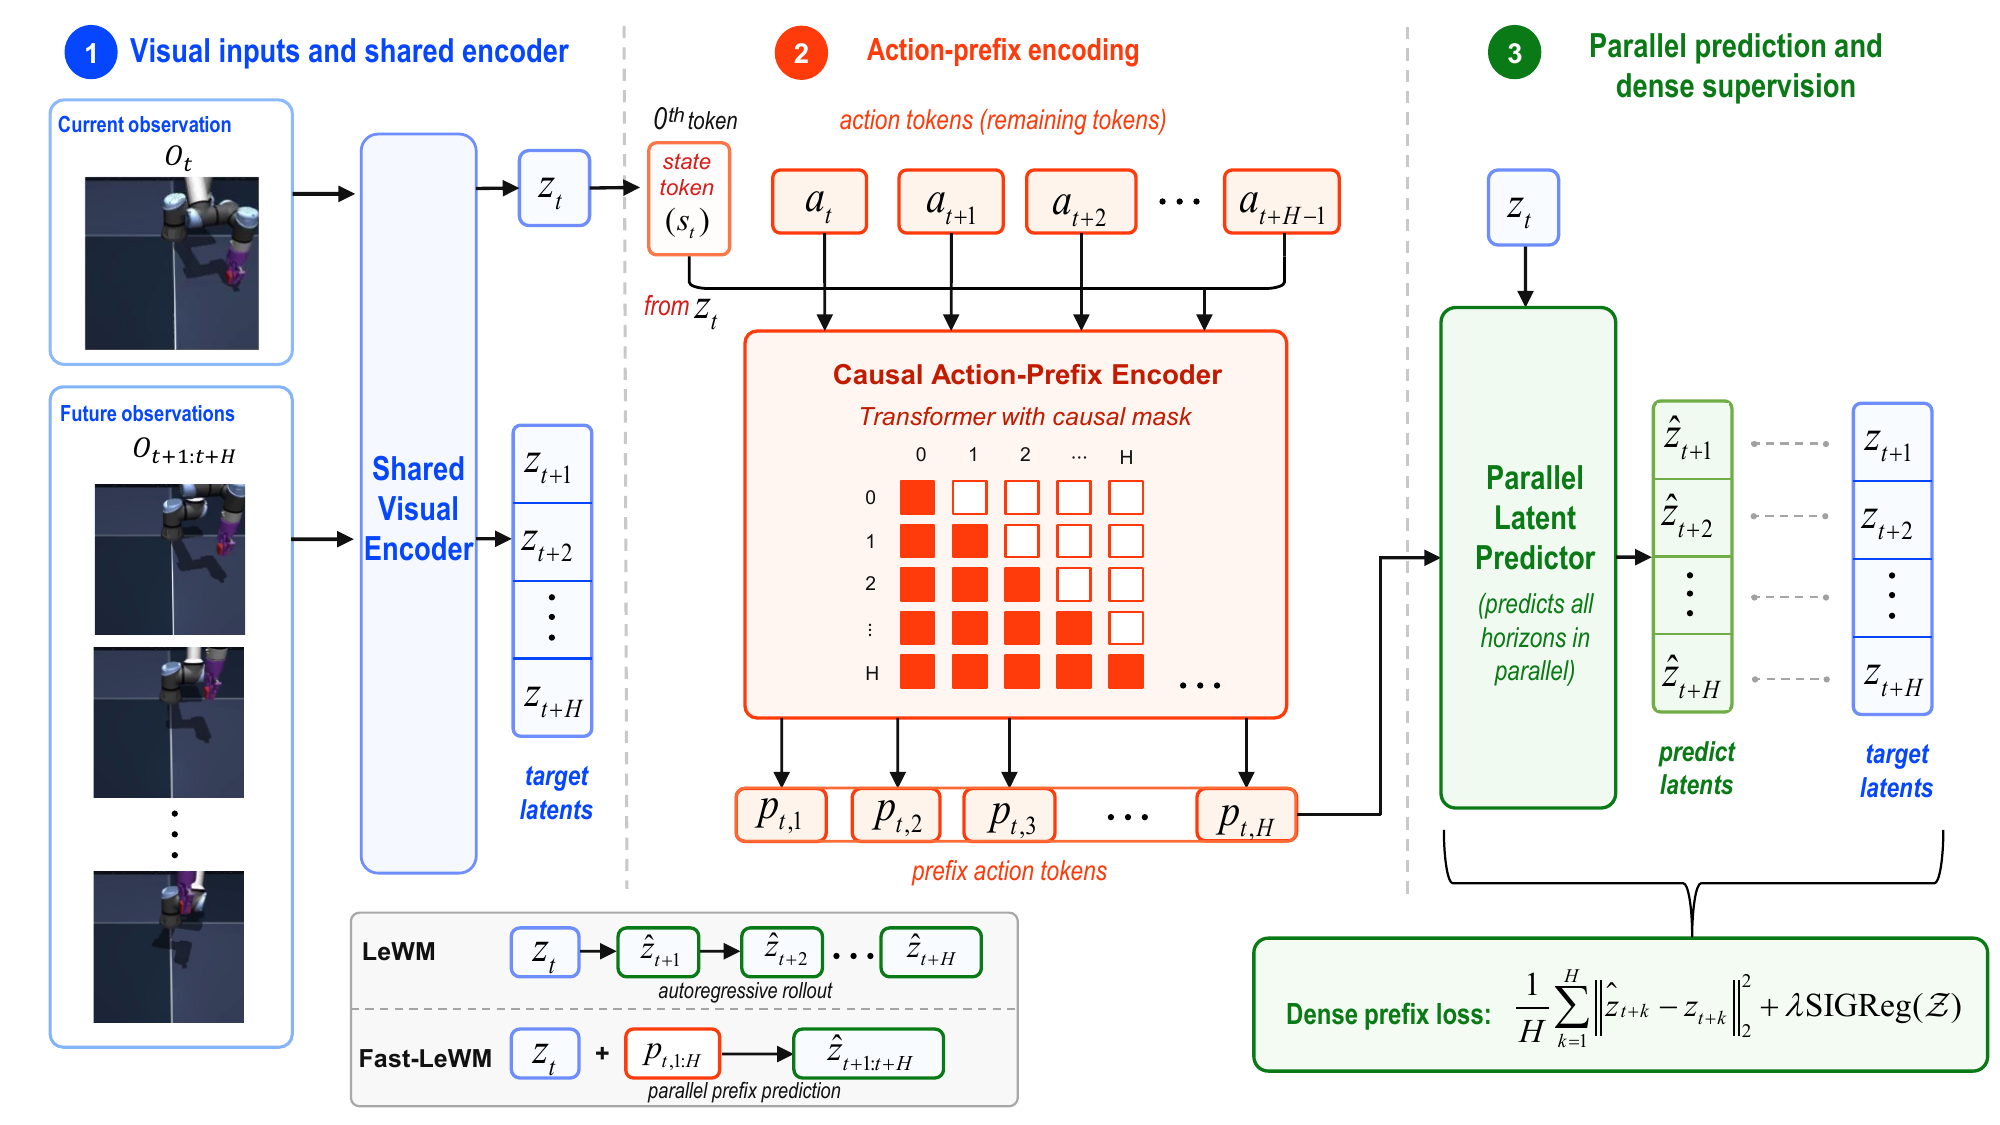
Fast-LeWM replaces repeated local rollout with action-prefix prediction. Given the current latent and a candidate action sequence, it encodes prefixes of that sequence and predicts the future latents reached after executing those prefixes in parallel. Joint multi-horizon training teaches the model how states evolve under different action prefixes. During planning, each future latent can be evaluated directly from its prefix without rolling through intermediate imagined states. Across four tasks, Fast-LeWM improves average planning success from 85.8% to 90.5% while reducing CEM solve time from 33.7s to 16.1s. It also lowers open-loop latent prediction loss and slows its growth over longer horizons.
Method: action-prefix prediction
Using prefixes of the candidate action sequence as multi-horizon queries, Fast-LeWM predicts future latents in parallel from the observed anchor latent.
Results
Fast-LeWM is evaluated on the same goal-conditioned planning tasks and protocol as LeWM: Two-Room, Reacher, PushT, and OGBench-Cube.
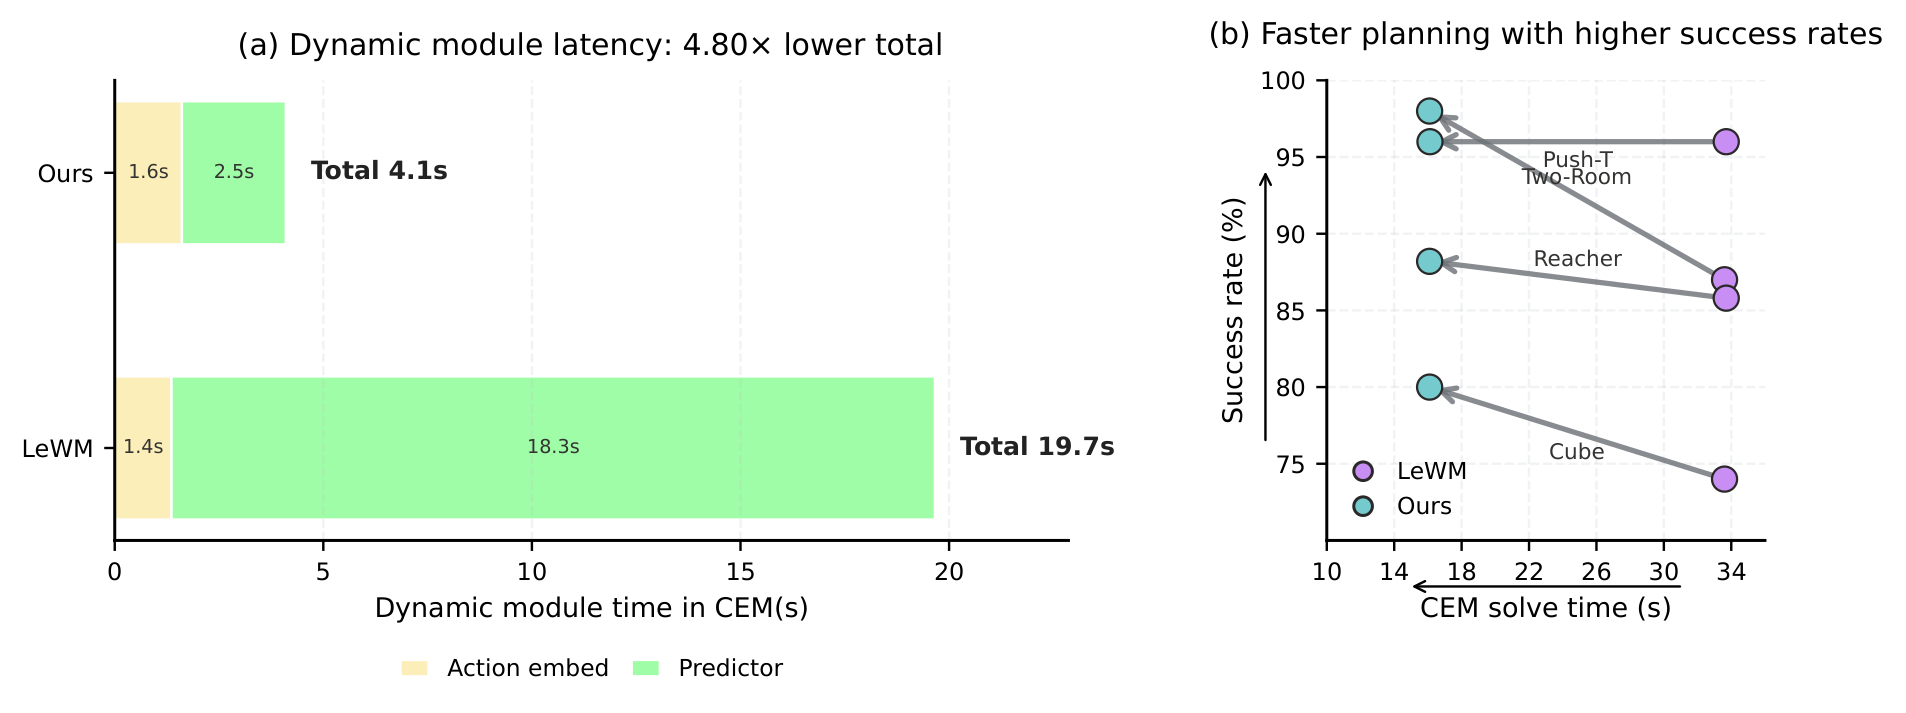
4.8x
faster dynamics evaluation: 19.7s to 4.1s.
52.2%
lower full CEM solve time: 33.7s to 16.1s.
90.5%
average success rate, improved from LeWM's 85.8%.
Planning success (%)
| Method | Two-Room | Reacher | PushT | Cube | Avg. |
|---|---|---|---|---|---|
| PLDM | 97 | 78 | 78 | 65 | 79.5 |
| DINO-WM | 100 | 79 | 74 | 86 | 84.8 |
| LeWM | 87 | 86 | 96 | 74 | 85.8 |
| Fast-LeWM | 98 | 88 | 96 | 80 | 90.5 |
| Fast-LeWM + Self-Consistency | 98 | 90 | 98 | 82 | 92.0 |
BibTeX
@misc{gao2026fastleworldmodel,
      title={Fast LeWorldModel},
      author={Yuntian Gao and Xiangyu Xu},
      year={2026},
      eprint={2606.26217},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2606.26217v2},
}